Q-learning grid world
Reinforcement learning · Q-learning · DQN · Gymnasium
A custom Gymnasium grid world and a tabular Q-learning agent that finds the best route in 17 steps, plus a DQN for a continuous maze.
Overview
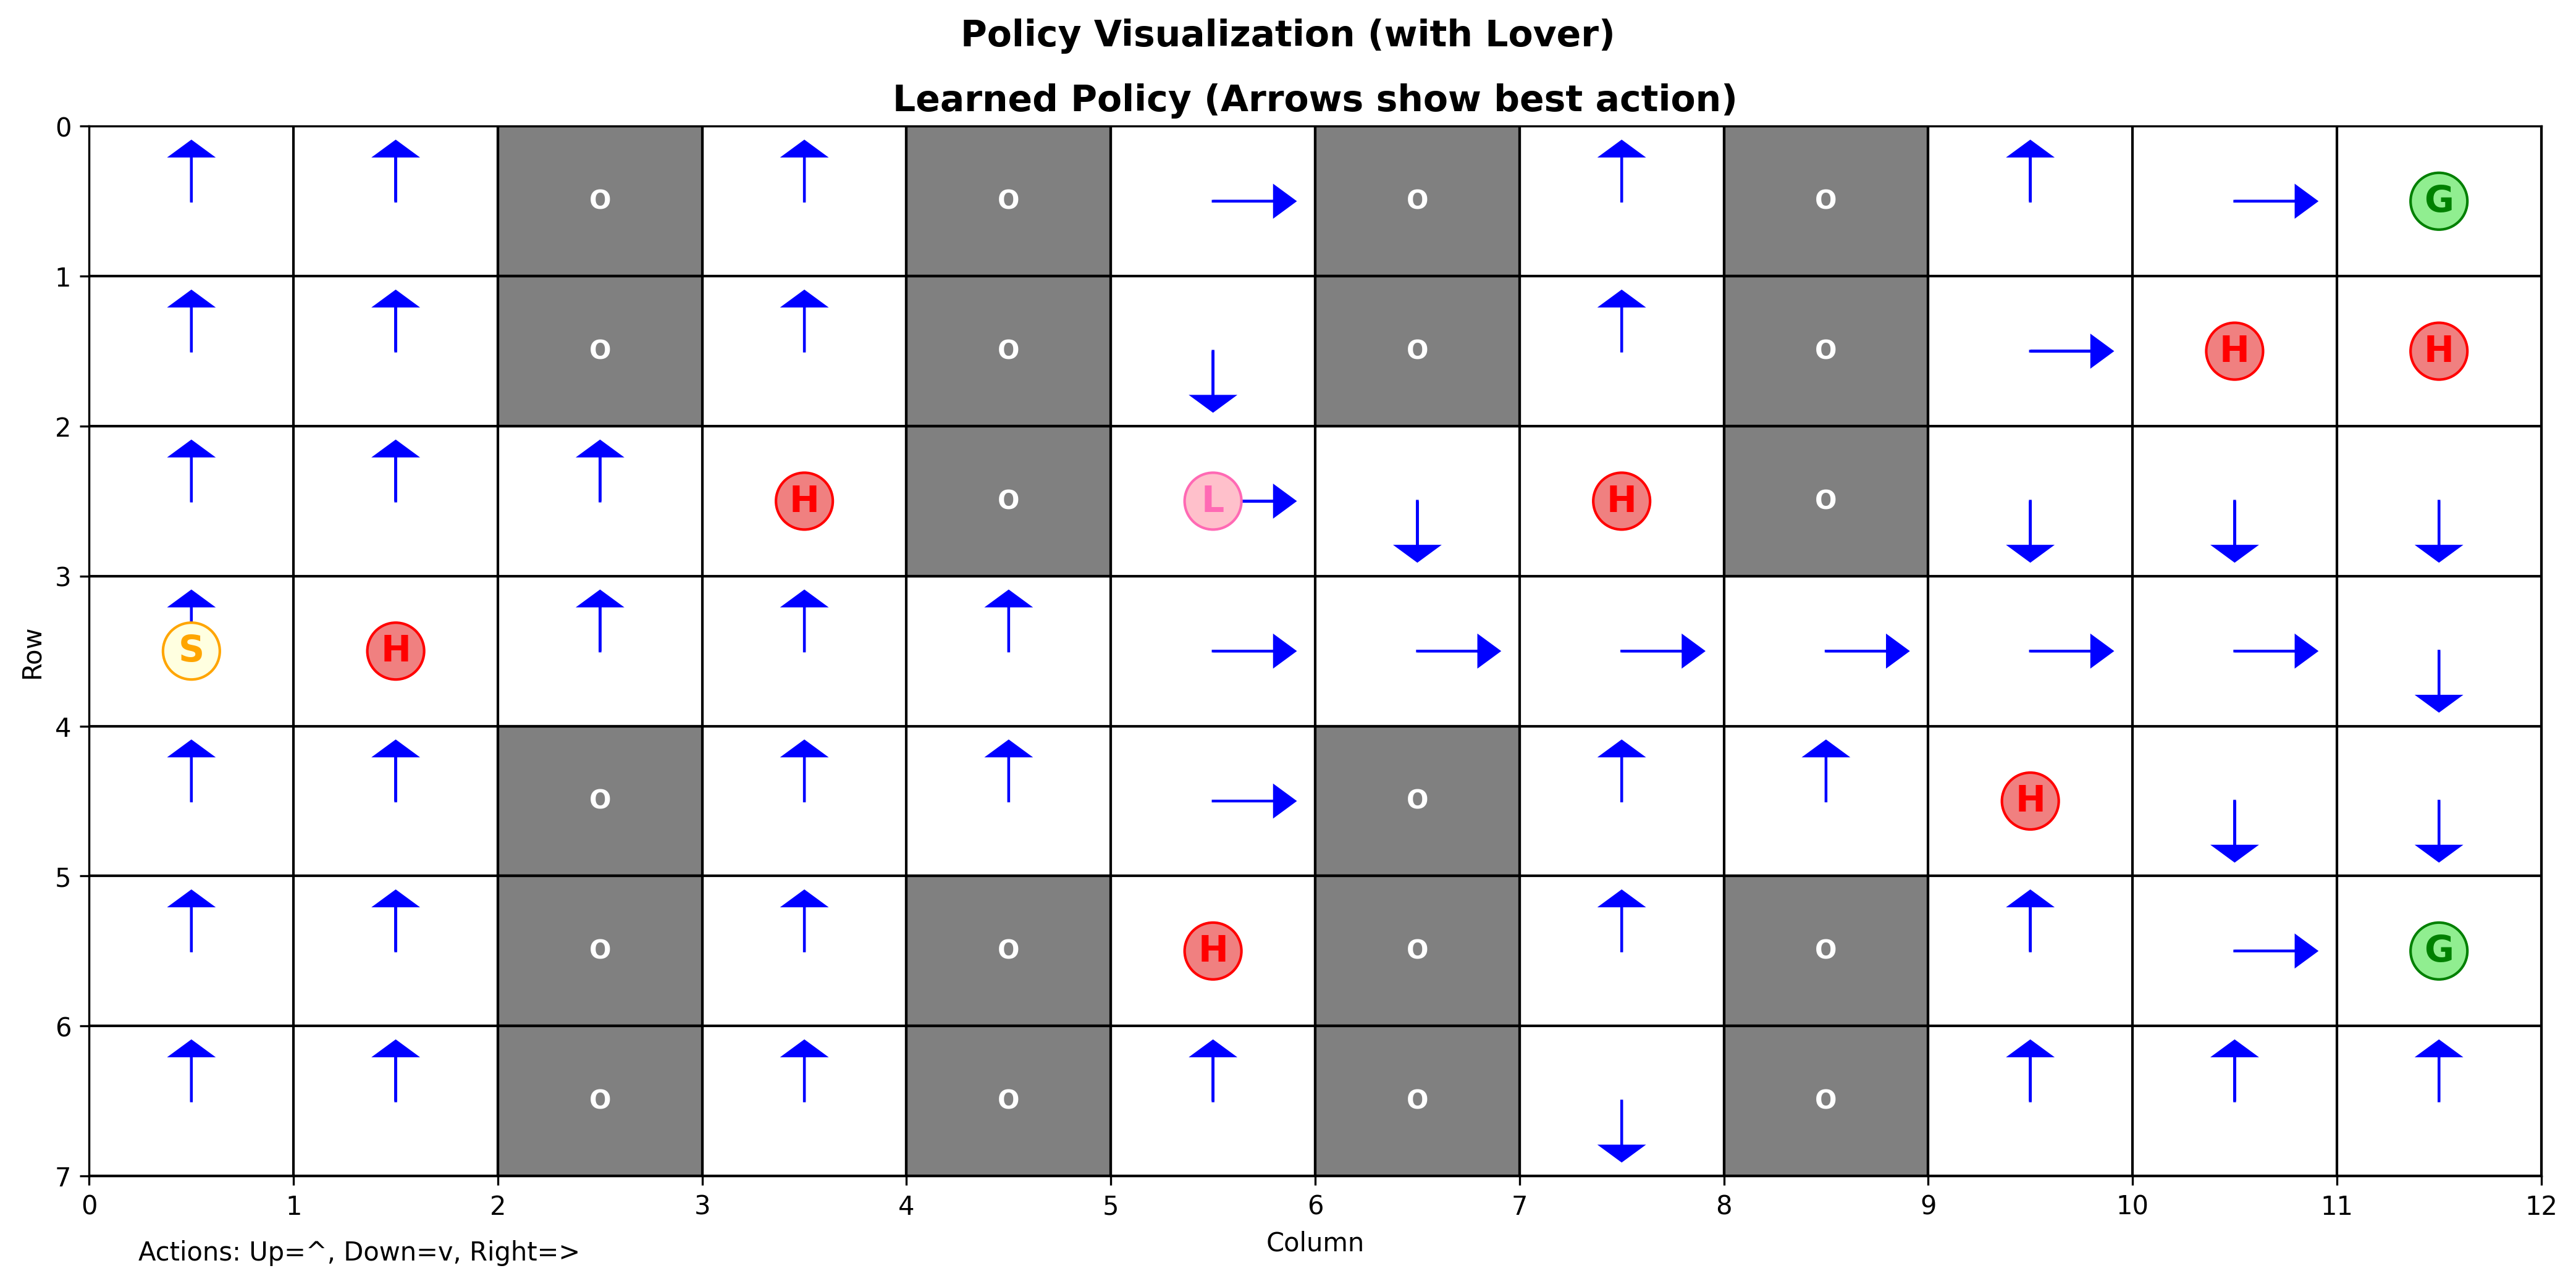
Three assignments from a course on planning and decision making: a custom grid world, a Q-learning agent that solves it, and a deep Q-network for a continuous maze. The grid world has an Ice Age theme, in which Scrat crosses a 7×12 grid of ice obstacles, danger zones and small rewards to reach one of two goals.
How it works
The environment follows the Gymnasium API, with three actions (up, down and right) and an observation of the row, the column and one flag: whether the agent has already visited the lover cell, which multiplies the goal reward by six. Because the flag is part of the state, the Q-table has four dimensions and the agent can learn one policy before the visit and another after it. Exploration is epsilon-greedy, with a reverse-sigmoid decay that stays exploratory early and settles late.
Result
After 500 training episodes the agent reaches a goal every time, by the best route: through the lover cell to the far goal, for a reward of 686 in 17 steps, where a random agent succeeds about 5% of the time. The DQN for the continuous maze, with experience replay and a target network, reached the goal in 100 episodes in a row. Heatmaps of the Q-values and arrow plots of the policy show what was learned.
Built with
Python · Gymnasium · NumPy · PyTorch · Pygame · Matplotlib